What Is Jev? System One Model Uses, Limits, and Pricing
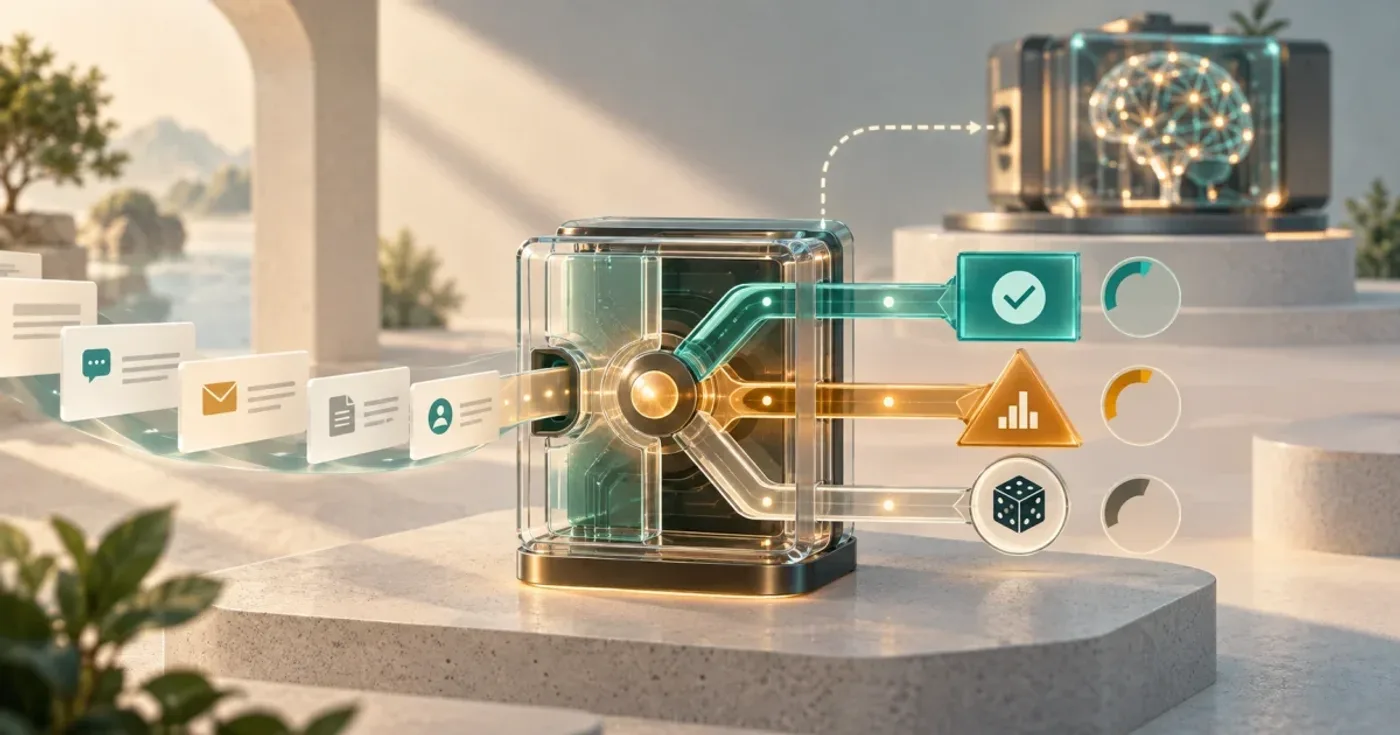
Jev is TypeSafe AI’s first public System One model. It does not write an answer, explain a decision, or generate code. You send a text or structured state plus questions with predefined answer shapes, and Jev returns probabilities that ordinary application code can evaluate.
That makes Jev relevant to classification, filtering, scoring, and routing. It does not make Jev a general replacement for an LLM. The useful decision is whether one small judgment in a workflow needs probabilistic language understanding without generated prose.
What Jev returns
The TypeSafe API exposes three question types:
| Primitive | Question shape | Response | Typical use |
|---|---|---|---|
Choice | Select one declared option | Selected key, probability per option, confidence | Intent classification, team routing, tool selection |
Score | Rate against an ordered rubric | Expected score, distribution, confidence | Urgency, risk, sentiment intensity |
Noul | Decide whether one statement is true | Probability from 0 to 1 | Spam detection, policy checks, prompt-injection flags |
Your program still owns the action. A high refund-request probability might add a ticket flag; it should not bypass order validation and issue a refund by itself.
This is also different from asking a chat model to emit JSON. Jev cannot invent a prose field outside the declared response type, but it can still select the wrong option or assign a misleading probability. Typed output removes parsing failures, not decision errors.
Where Jev fits—and where it does not
Use Jev when the state contains language or loosely structured data and the output space is known in advance:
- Route support tickets to a fixed set of teams.
- Rank retrieved passages for a downstream answer.
- Estimate whether a message satisfies one policy condition.
- Select an agent tool from a controlled catalog.
- Score urgency against a rubric your application defines.
Choose another mechanism when the task needs something else:
| Requirement | Better default | Why |
|---|---|---|
| Exact amount, date, count, or identifier | Parser, database query, or deterministic code | TypeSafe documents numerical precision, counting, and dates as jagged areas. |
| A user-facing explanation or new text | Generative model | Jev does not generate strings. |
| Multi-step planning or code changes | Reasoning model or coding agent | Jev answers independent typed questions; it does not execute a plan. |
| A stable rule already expressible as code | Ordinary code | A model adds latency and uncertainty without adding language understanding. |
| High-impact action | Model signal plus verified rules and review | Confidence is not a guarantee that the answer is correct. |
Current model, price, and limits
As checked on September 22, 2026, TypeSafe lists Jev 1.13 as jev-1.13.0. The managed API price is $0.042 per million input tokens, with output tokens free. Published limits are 250,000 tokens per second and 1,200 requests per minute, although TypeSafe says those limits can change during early access.
The request budget is 64,000 tokens in total and 32,000 tokens for the state plus the longest question. Input is text only; images, audio, and binary files must be converted into text or structured fields first.
English is the primary training language. TypeSafe says CJK and other languages are supported unevenly, so a non-English workflow needs its own labeled evaluation rather than an English threshold copied into production.
How to read the speed claims
TypeSafe advertises results as high as 193.6 times faster and 444.6 times cheaper than compared LLM workflows. Those are vendor workflow benchmarks for System One tasks, not a promise that every request will achieve the same ratio.
The comparison is favorable by design: Jev gives up text generation and solves a narrower problem. That trade is useful when the application needs only a decision. It says little about tasks that require explanations, tool execution, or long reasoning chains.
Measure an actual candidate workflow instead:
- Build a labeled set from the application’s real traffic.
- Record accuracy, calibration, latency, and cost for the current path.
- Test Jev with the same inputs and explicit criteria.
- Include the fallback path in both cost and latency totals.
- Keep versioned results;
jev-latestcan move to a new model.
A sensible rollout boundary
Start in shadow mode. Keep the existing route active while logging Jev’s versioned model ID, probability distribution, latency, and eventual ground-truth label. Avoid copying sensitive source text into an uncontrolled log.
Only automate a branch after the error cost and review threshold are explicit. If a low-confidence fallback sends nearly every item to an expensive model, the architecture may still be correct, but the expected cost reduction will not materialize.
For an implementation example, continue with the Jev TypeScript API guide. If the goal is to reduce coding-agent usage, read the Jev and Codex token-savings analysis before installing a skill. For data that must remain local, compare the Laya local decision model.
FAQ
Q: Is Jev a small language model?
A: Jev consumes natural-language text, but its public interface is a decision API rather than a text generator. It answers Choice, Score, and Noul questions with typed probabilities and cannot produce an open-ended response.
Q: Does Jev confidence mean the answer is correct?
A: No. Confidence describes the model’s reported certainty or concentration for that decision. Validate it on representative labeled data, set an application-specific threshold, and retain a fallback for costly mistakes.
Q: Can Jev replace a large language model?
A: It can replace narrow classification or routing calls when the answer space is fixed. It cannot replace a model that must explain, plan, write code, or generate new user-facing content.
References: