Does Jev Save 90% of Codex Tokens? Skill and Router Limits
Claims that Jev can cut Codex token usage by 90% combine several different integrations: installing the TypeSafe agent skill, letting Codex call the Jev API, exposing Jev through MCP, and placing a model router in front of coding turns.
Installing the skill alone does not intercept context that Codex has already read, replace the model for every turn, or create an external proxy. A measurable saving requires changing which work reaches the large model or which model handles a turn.
What the TypeSafe skill installs
The official command is:
npx skills add typesafe-ai/skills --skill typesafe-aiThe installed skill gives an agent instructions for reading TypeSafe documentation, choosing Choice, Score, or Noul, designing criteria, calling the API, and interpreting probabilities. A skill is context and procedure for the agent. It is not a transparent network router.
This distinction matters because Codex must still load the task, repository instructions, and skill content before it decides to call Jev. Delegating a small classification after that point may reduce later reasoning, but it does not refund the input already processed by Codex.
Four integration patterns with different cost effects
| Pattern | What changes | Can it reduce large-model work? | Main caveat |
|---|---|---|---|
| Agent skill | Codex learns how and when to call TypeSafe | Sometimes, after Codex makes the decision | Adds instructions and a tool call; no automatic model switch |
| Direct API call | Application code sends a bounded decision to Jev | Yes, if the decision replaces an LLM call | Requires explicit orchestration and fallback |
| MCP server | Jev becomes an agent-accessible tool | Sometimes | The host model still decides whether to invoke it |
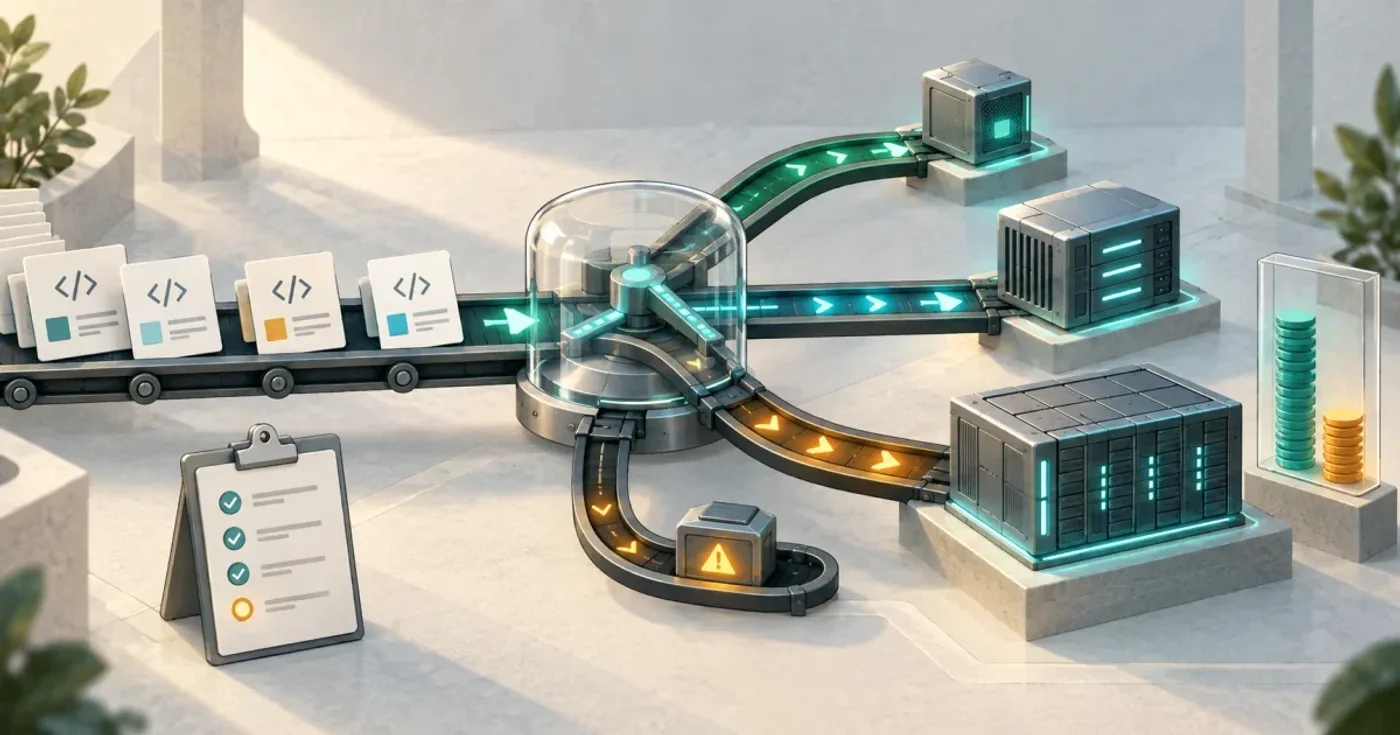
| External router | A component selects a model before a turn | Potentially the largest reduction | A wrong route can reduce quality or require an expensive retry |
The fourth pattern is the only one that can keep an easy turn away from the stronger model before that model sees the prompt. It is also the pattern with the highest evaluation burden.
What the 237-turn backtest reports
The community jev-codex-router project replayed 237 historical turns from seven days of one user’s Codex activity. Its published simulation estimated a baseline cost of about 349, a reduction of 59.9%.
That result is useful as a hypothesis, not proof of equivalent production performance. The repository documents several limitations:
- It is a retrospective simulation, not live routed traffic.
- The calculation assumes constant token volume for a turn after changing models.
- It does not model cache invalidation caused by switching models.
- The workload belongs to one user and one historical period.
- It does not run the chosen model and compare correctness, review time, or accepted patches.
- Current routing policy behavior was not independently measured here.
The reported figure also does not establish a general 90% reduction. Different model prices, task mixes, cache behavior, and failure rates can move the result in either direction.
Measure the whole workflow, not one API call
A useful evaluation records more than Jev’s low input price:
total cost= router decision+ selected model turn+ cache misses caused by switching+ retries and escalations+ validation and review workTrack at least:
- Cost per completed and accepted task.
- Percentage of turns escalated to the stronger model.
- False-easy routes that later require rework.
- Test, review, and task-completion outcomes by route.
- End-to-end latency, including fallback.
- Cache-read and cache-write changes after model switches.
The existing Copilot per-model token report guide shows why input, output, and cache columns need separate interpretation. A lower raw token total does not prove a better development result.
A lower-risk way to start
Use Jev first for decisions whose mistakes are cheap and observable: labeling incoming issues, ranking search candidates, selecting a read-only tool, or deciding whether a result needs manual review. Keep build failures, security-sensitive changes, migrations, and ambiguous multi-file work on the stronger path until the router has evidence for those categories.
For each route, log the Jev model version, probabilities, selected path, eventual outcome, and fallback reason. Do not log secrets or full repository context merely to make the router auditable.
The Jev capability guide explains which decisions match the model. The TypeScript API example shows how to keep thresholds and actions in code. If a managed API is unsuitable, Laya provides a local model path, with different hardware and accuracy trade-offs.
FAQ
Q: Does installing the TypeSafe skill automatically reduce Codex tokens?
A: No. The skill supplies instructions that help Codex use TypeSafe. Codex still processes the task and skill before deciding whether to call Jev, so savings depend on the orchestration that follows.
Q: Is the 59.9% Jev Codex Router result a real production saving?
A: It is a historical cost simulation over 237 turns. It did not rerun every task on the selected model, establish equal output quality, or model all cache effects. Treat it as a testable estimate for that workload.
Q: When can a router reduce the most large-model usage?
A: A router has the greatest leverage when it acts before the expensive model receives a turn. That also makes routing mistakes more consequential, so evaluate completion quality and fallback cost alongside the model bill.
References: