GitHub Actions Pending Runs Cancelled? Use queue: max
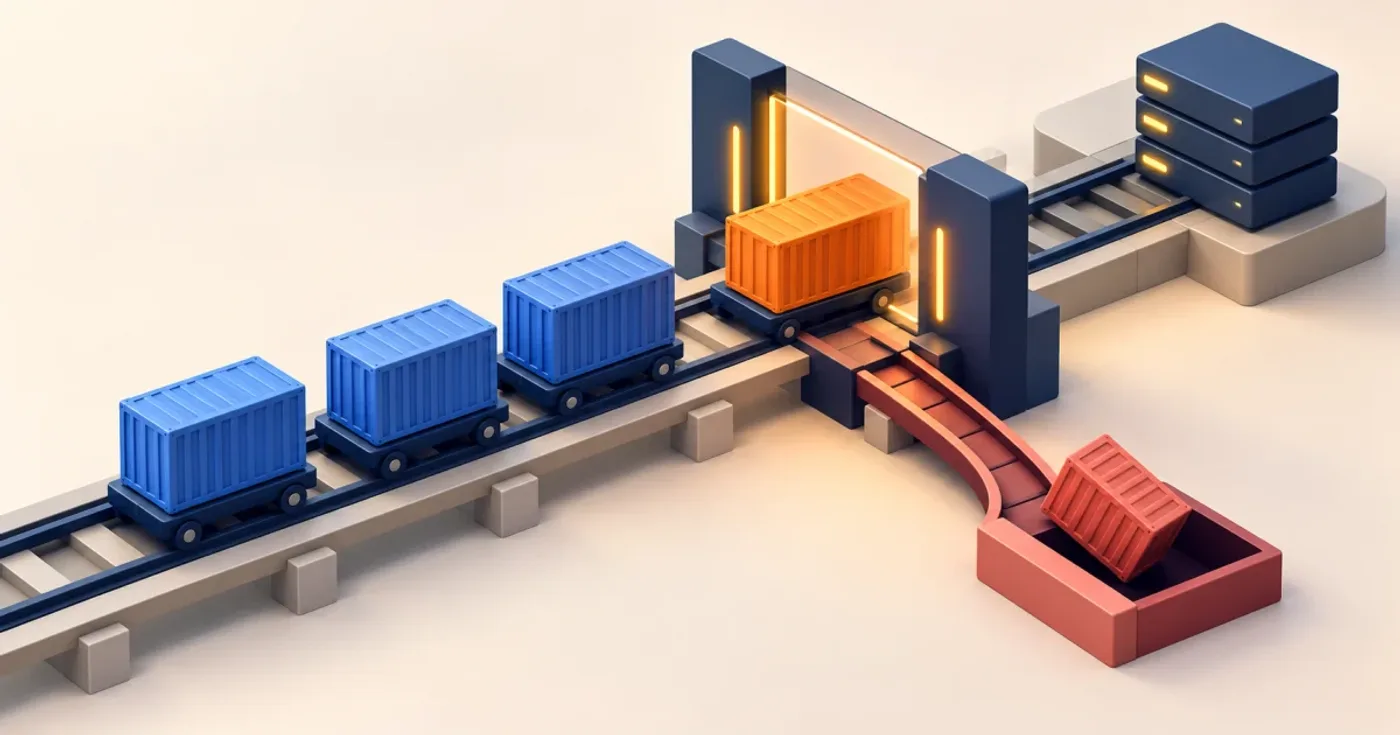
If GitHub Actions cancels a pending deployment despite cancel-in-progress: false, check the concurrency queue policy. That setting preserves the running job; the default queue still replaces an older pending job when another arrives. Set queue: max when later deployments should wait instead.
GitHub introduced larger concurrency queues on May 7, 2026. Advice that native concurrency can only retain one waiting run describes the default policy, rather than the only available configuration.
Separate running cancellation from pending replacement
Consider three jobs entering the same group: A is running, B is waiting, and C arrives. Under the default queue: single, C replaces B even when A is protected by cancel-in-progress: false.
With queue: max, both B and C can wait behind A. The limit is 100 pending jobs or workflow runs per group; additional arrivals are canceled when that queue is full. Combining queue: max with cancel-in-progress: true produces a validation error. These boundaries come from the current concurrency documentation.
Use this block for a deployment target shared by jobs in the same repository:
concurrency: group: production-deploy cancel-in-progress: false queue: maxKeep the group stable across workflows that mutate that target. GitHub’s Branch Deploy guidance uses this pattern to coordinate shared deployment work and distinguishes execution concurrency from deployment ownership locks.
Choose the group around the resource
The useful question is which jobs must avoid overlapping writes. A group based on a workflow name can separate two pipelines that both deploy to the same service.
| Work you need to coordinate | Group choice | Reason |
|---|---|---|
| Two workflows deploy the same production service | The same fixed key, such as production-deploy | Both pipelines contend for one target |
| Preview deployments have separate targets per branch | A target-specific key containing the branch | Independent previews need separate coordination |
| Every run has its own isolated destination | A per-run key, or no concurrency block | There is no shared destination to serialize |
This table applies the shared-resource guidance above; it is not a benchmark or a guarantee of deployment safety. In particular, environment: production does not automatically put jobs into a common concurrency group. GitHub’s deployment documentation treats environment protection and concurrency as separate controls. A workflow without the matching concurrency setting can still bypass your chosen coordination boundary.
Verify with three harmless manual runs
Before applying the policy to production, create .github/workflows/queue-demo.yml in a disposable test repository. Put it on the default branch so manual dispatch is available. The job below logs a marker and waits; it does not check out code or deploy anything.
name: Concurrency queue demorun-name: Queue demo ${{ inputs.marker }}
on: workflow_dispatch: inputs: marker: description: Label for this run required: true type: string
permissions: {}
jobs: hold: runs-on: ubuntu-latest timeout-minutes: 5 concurrency: group: queue-demo cancel-in-progress: false queue: max steps: - name: Hold the group briefly env: MARKER: ${{ inputs.marker }} run: | printf 'start %s\n' "$MARKER" date -u sleep 90 printf 'end %s\n' "$MARKER" date -uThe marker enters the shell through an environment variable instead of being inserted directly into the script. Use labels A, B, and C, and perform the check in this order:
- Dispatch A and wait until its log shows
start A. - Dispatch B while A is sleeping. Confirm B is waiting on the group.
- Dispatch C before A finishes. Inspect whether B remains pending.
- Let the jobs finish and compare their start/end timestamps.
With queue: max, the expected outcome is that A, B, and C all complete without overlapping their hold steps. To compare the default policy, finish every demo run first, remove only queue: max, and repeat the sequence. B should be replaced when C joins while A still holds the group.
Those outcomes are expectations derived from GitHub’s documented policy, not results from an executed hosted experiment. If A finishes before C reaches the group, the test has not exercised pending replacement; repeat with a longer hold and adjust the timeout accordingly. No other workflow should use queue-demo during this check.
The workflow syntax reference supports job-level concurrency, so builds in earlier jobs can proceed before the deployment job acquires its group. That separation is useful, but it also changes when jobs join the queue.
A deployment queue does not establish commit order
GitHub documents FIFO processing by the time each job or run starts waiting on the concurrency group, rather than by workflow dispatch time. Suppose an older commit needs a slow build while a newer commit finishes its build quickly. The newer deployment can reach a job-level group first. Serial execution alone does not prevent the older artifact from deploying afterward.
For a release pipeline, decide separately whether every revision must deploy or whether a stale revision should be rejected before mutation. Record the artifact revision and the deployed revision so that this decision can be checked; queue: max supplies waiting capacity, not a revision policy.
If a job appears unable to cancel, inspect its if condition as a separate issue. The workflow cancellation reference explains that GitHub re-evaluates job conditions during cancellation and can keep work running when a condition such as always() remains true. Do not add that condition merely to keep a deployment queue alive.
Use a shared group and queue: max when each waiting deployment should retain its place, then verify the queue with harmless runs before connecting real deployment commands. For concurrency inside one job, see the separate parallel steps guide; it addresses a different scheduling boundary.
References:
GitHub Changelog: Concurrency groups now allow larger queues
GitHub Docs: Control workflow and job concurrency
GitHub Docs: Control deployments